Push
Multi-Task ES+ES (Oracle)
Video unavailable. Open recording
Multi-Task ES+SS (Ours)
Video unavailable. Open recording
State-of-the-art vision-language-action (VLA) models such as π0.5 exhibit strong semantic understanding, instruction following and task behavior. However, when deployed on new robots, even minor mismatches in hardware configuration relative to pretraining can cause severe performance drops. Finetuning the VLA on in-domain expert data from the new embodiment improves performance on the expert task but leads to a loss in its original instruction following and behavioral priors. In this paper, we propose a self-supervised method that generates online interaction rollouts from the zero-shot VLA as additional training data for finetuning. Our experiments show this yields strong multi-task manipulation policies on the target robot that (1) inherit pretrained tasks distilled from the zero-shot VLA without expert demos for them, (2) improve success and generalist instruction following beyond expert-only fine-tuning on expert-teleoperated tasks, and (3) mitigate forgetting of held-out tasks from the pretrained policy, not part of fine-tuning. We demonstrate the success of our approach across test sets probing generalization on a real ALOHA robot and a new simulation benchmark in RoboTwin.
We leverage these priors through self-supervised generative control [Self-Demonstration]We rollout the policy online on our robot, asking it to show us how to do the task
BENCHMARK 1 · PICK AND PLACE · TSS
Self-supervised task, distilled purely from self-demos, no expert data collected
Video unavailable. Open recording
Video unavailable. Open recording
Video unavailable. Open recording
20 evaluation trials per policy
pick-and-place success, with no expert place demonstrations 20 evaluation trials
Task-behavior transfer · the expert data contains pick-up, not placing.
What if we recollect the pick-and-place data on our robot? Comparison against upper bound.
Video unavailable. Open recording
Video unavailable. Open recording
Video unavailable. Open recording
Video unavailable. Open recording
Held-out skills not part of any fine-tuning data source are preserved even when compared to upper bound! Results from a human user study show that self-demos are preferred in blind comparisons.
Success rate (correct object) p<0.001
While IF is comparable across the 2 policies (82% and 84%), motion prior is far better retained by our method.
Success rate (correct object) p<0.001
While IF is comparable across the 2 policies (91% and 97%), motion prior is far better retained by our method.
6 raters · 240 paired blind judgments · 20 scenes per task
ES+ES collects expert demonstrations for all tasks on our robot, replacing self-demos.
BENCHMARK 2 · COLORED BIMANUAL GEAR INSERTION
Expert-supervised task, self-demos improve performance
Video unavailable. Open recording
Video unavailable. Open recording
Video unavailable. Open recording
10 evaluation trials per policy
gear insertion success with expert gear colors 10 evaluation trials
BENCHMARK 2 · UNSEEN GEAR COLORS
Expert-supervised task · OOD gear colors
Video unavailable. Open recording
Video unavailable. Open recording
Video unavailable. Open recording
10 evaluation trials per policy
gear insertion success with unseen colors 10 evaluation trials
Real robot test sets span
Task success (%)
Controlled embodiment gap (E2)
Changing only the head-camera view drops old-task success from 90.8% to 51.6%; expert-only post-training lowers it further to 21.4%, while adding self-demos improves it to 36.0% (+14.6 percentage points).
Old tasks (TSS), evaluated in the topview mean over 10 tasks × 50 seeds
New tasks (TES): topview stacking 2 tasks × 50 seeds
Our real-robot self-demos are all task failures, yet much of their behavior is semantically meaningful. In the 15 analyzed rollouts, 94% of grasp attempts and 89% of place attempts target the instructed object or container, but no grasp succeeds.
13 of 15 episodes retry, with a mean of 2.1 grasp attempts and 1.2 place attempts per episode.

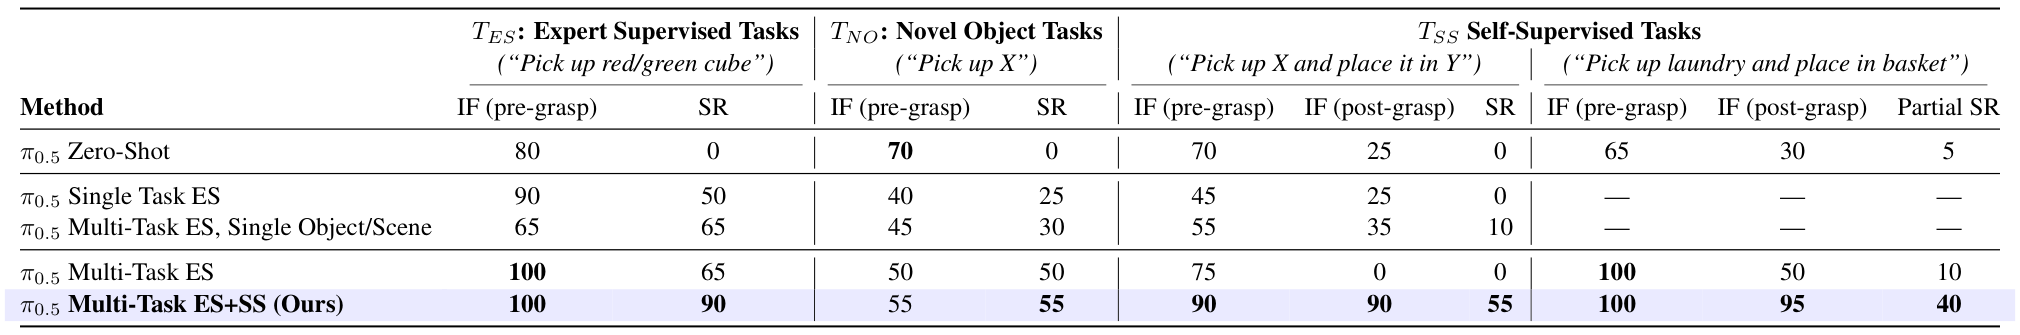
IF (post-grasp) measures how often the arm moves to the correct container after an attempted pick-up.
Even when expert data covers the same pick-and-place task, adding self-demos raises success from 55% to 65% (Table 9).
| Pick-and-place training | IF (pre-grasp) | IF (post-grasp) | Success rate |
|---|---|---|---|
| Multi-Task ES | 75% | 85% | 55% |
| Multi-Task ES+SS (Ours) | 95% | 80% | 65% |
Personalized distillation. Our policy produces smooth rollouts that complete self-supervised tasks, with motions personalized to our robot. The zero-shot base policy is jerkier, often raises both arms higher than the task requires, and is unable to grasp, with 0% task completion on pick-and-place.
Recovery behavior. Ours has better recovery behavior when objects sit at table edges: it turns to look for objects behind the wrist camera, unlike the baselines. We suspect this comes from the broader task and state coverage of self-demos on the robot.
TL;DR of results: Post-training VLAs with policy's self-supervised online rollouts on the target robot distills pretrained skills, improves expert task performance, and preserves held-out skills. Yields a generalist, multi-task manipulation policy at deployment.
Takeaway: To mitigate forgetting:
@misc{garg2026finetuningvlasselfdemonstratedgenerative,
      title={Fine-Tuning VLAs with Self-Demonstrated Generative Control for Multi-Task Manipulation},
      author={Prachi Garg and Steve Xing and Prahit Yaugand and Saurabh Gupta and Derek Hoiem},
      year={2026},
      eprint={2608.19490},
      archivePrefix={arXiv},
      primaryClass={cs.RO},
      url={https://arxiv.org/abs/2608.19490},
}